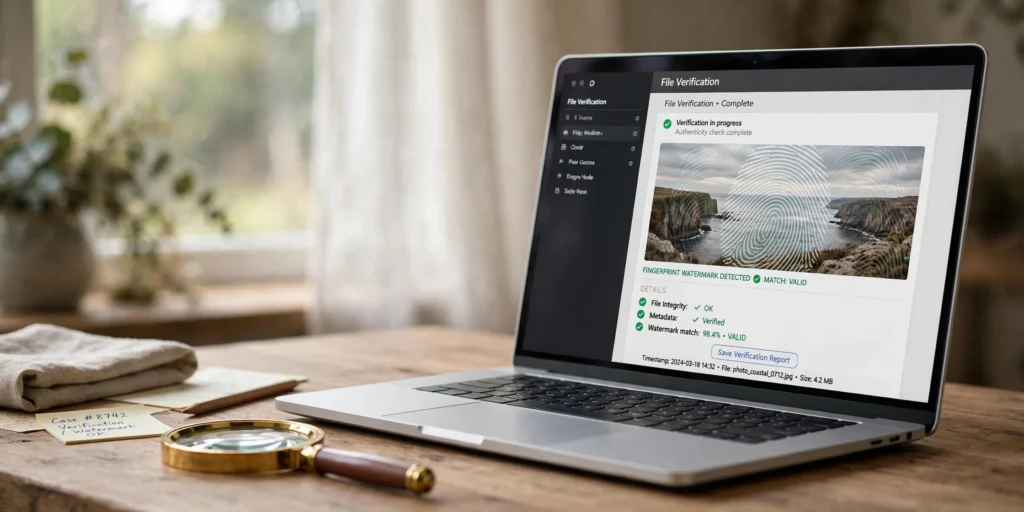
Google put its AI watermark checker in the hands of everyone on October 7, and the move matters more for content practitioners than it looks at first glance. The SynthID Detector, a verification portal at synthid.com that was previously limited to journalists, researchers and media professionals through a waitlist, is now open globally in English. Anyone can upload an image, video or audio file and check whether it carries an invisible SynthID watermark from Google or its partners OpenAI, NVIDIA and Kakao, with Apple expected to join soon. The announcement came through a post on The Keyword by Pushmeet Kohli, Google DeepMind’s VP of Science and Strategic Initiatives.
The scale numbers Google shared are worth sitting with for a moment. Since SynthID launched in 2023, the company says it has watermarked more than 180 billion images and videos, plus the equivalent of 240,000 years of audio. Verification features already built into Search, the Gemini app and Chrome now handle over one million requests a day between them. That is a lot of content provenance being checked quietly in the background while the industry argues about whether AI-generated content is detectable at all. The detector also handles video and audio, and for those formats it can indicate where in the file a watermark appears, which is a genuinely useful forensic detail for anyone auditing content pipelines.
The most important sentence on the whole SynthID Detector site might be in its FAQ, where Google states plainly that this is not a general AI detector. It only identifies media from companies that have adopted SynthID technology, and finding no watermark does not prove a file is genuine, since it may have been made by a tool that never embeds one or the signal may have weakened after heavy editing. That honesty is refreshing, and it also sets the practical boundary for anyone thinking about using this as some kind of content quality gate.
What this means for people publishing content
- Watermarked provenance is becoming infrastructure, not a novelty, and practitioners should treat media origin the way they treat authorship, as something worth documenting and verifying.
- The partner list is the story to watch, since detection currently covers Google, OpenAI, NVIDIA and Kakao with Apple on the way, and the value of the portal grows with every maker that joins.
- Anyone running content operations should test the detector against their own media, because knowing what your output looks like through a provenance lens is the same discipline as checking how your pages render in Search.
Failon’s POV: provenance is the new authorship signal
I have spent years telling clients that trust signals compound, and provenance just became one of the few trust signals you can verify with a URL. The practical play here is not to obsess over whether competitors watermark their media, but to make your own media traceable and clean, because a detection layer that handles a million requests a day will quietly separate content with provenance from content without it. That separation is exactly the kind of thing generative engine optimization strategies need to account for, since answer engines are already leaning on provenance signals to decide what to cite. If you are publishing AI-assisted media at any scale, watermarked output from participating tools is now the defensible position, and this detector is the receipts page. I would rather my clients be the ones whose media verifies cleanly than the ones explaining an ambiguous result.